Free course · Python · NumPy · scikit-learn · PyTorch

Machine Learning, from Linear Models to Deep Vision

A hands-on course that starts with a nearest-neighbour classifier and ends with a diffusion model generating data from noise. Every algorithm is first written from scratch in NumPy or PyTorch, checked against the library you would use in practice, and run on real data — and every number and figure on these pages is the actual output of the code.

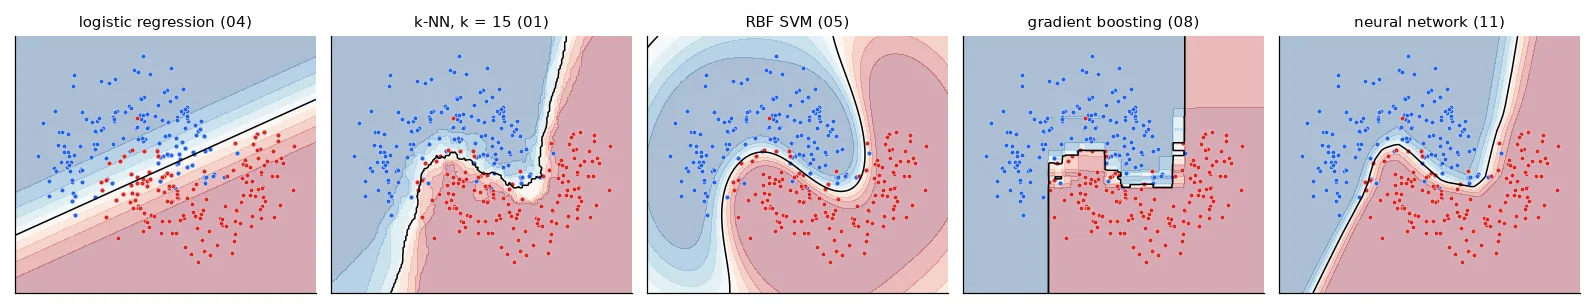
Decision boundaries of logistic regression, k-NN, an SVM, gradient boosting and a neural network on the same data

About this course#

This course grew out of two university courses I took — Introduction to Machine Learning at INSA Rouen Normandie (France) and Deep Learning at UFRN (Brazil) — and the deep learning I use in my research on autonomous drones and boats. I rewrote all of it as one path, in English, moved the deep learning to PyTorch, re-ran every experiment, and fixed the mistakes I made the first time. The mistakes are still there, in red boxes: un-normalised inputs that cost 50 points of accuracy, a model tuned on its own test set, an optimiser comparison where the optimiser never changed. They teach more than the parts that worked.

Each lesson follows the same rhythm:

  1. The idea — the problem, and the maths behind it, kept short.
  2. From scratch — an implementation you can read line by line: k-NN, gradient descent, an SVM dual, CART, AdaBoost, k-means, PCA, backpropagation, non-maximum suppression, ArcFace, a diffusion model…
  3. The library way — the scikit-learn, PyTorch or Ultralytics call you would use in a real project, and a check that both agree.
  4. Run it — every lesson is a single script. Run it, change a hyper-parameter, run it again.
  5. Pitfalls — the bugs I actually hit, so you don't have to.

Who it is for#

Students and engineers who know Python and some linear algebra and want to understand machine learning instead of copying model.fit(). Parts I–III need high-school calculus (a derivative, the chain rule). Part IV builds neural networks from the ground up, and Part V applies them to vision. If you are new to images, the Computer Vision course is the natural companion: it covers the classical side — filters, features, geometry — that this course builds on in lessons 13–16.

How to follow it#

Start with lesson 00 to install the environment and download the code. Parts I–III can be read in order or picked à la carte; lesson 06 (model selection) is the one not to skip. Part IV builds up in order (11 → 12 → 13 → 14), and each lesson of Part V stands on its own once Part IV is done.

Where this leads

Lessons 13–16 are the toolbox behind my projects: boat perception with a custom YOLOv11 detector for an autonomous surface vessel, drone target tracking with a custom YOLOv8 model, and monocular depth on a drone with pretrained networks.

Part I Foundations

00 Setup and how the course code works Install Python, scikit-learn and PyTorch in a virtual environment, download the code, and learn the conventions every lesson script follows — seeds, configuration objects, shapes in comments, and datasets that download themselves. venv · pip · PyTorch CPU/GPU · project layout · reproducibility 01 Data, splits and a first classifier Load a real dataset, look at it before touching a model, split it into training, validation and test sets, and classify wines with k-nearest neighbours — written from scratch, then with scikit-learn. Along the way, the two ideas that run through the whole course — overfitting and feature scaling. pandas · stratified split · k-NN · overfitting · standardisation · data leakage 02 Linear regression and gradient descent Fit a line three ways — the closed-form formula, least squares, and gradient descent written by hand — and understand the learning rate, why feature scaling makes optimisation fast, and how a polynomial with too many degrees of freedom memorises noise. least squares · MSE · gradient descent · learning rate · conditioning · polynomial features · ridge 03 Optimisation for machine learning Every model in this course is trained by minimising something. Compare fixed-step gradient descent, Armijo line search and Newton's method on the Rosenbrock function, check gradients numerically, then solve constrained problems with CVXPY — primal, dual, KKT multipliers — up to the minimum enclosing ball and its soft, outlier-tolerant version. gradient · Hessian · line search · Newton · Lagrangian · duality · CVXPY

Part II Supervised learning

04 Logistic regression The workhorse of classification. Derive the cross-entropy loss from probabilities, train logistic regression by gradient descent in ten lines, build a spam filter whose weights you can read, and extend it to ten classes with the softmax — the exact output layer of every classification network in Part IV. sigmoid · cross-entropy · maximum likelihood · log transform · odds · softmax · MNIST 05 Support vector machines The classifier with the widest margin. Write the SVM as the optimisation problem it is and solve it with CVXPY, see what C really does, derive the dual, and use it to draw curved boundaries with the kernel trick — an RBF SVM written from scratch that agrees with scikit-learn on every point. margin · hinge loss · soft margin · support vectors · dual · kernel trick · RBF · grid search 06 Model selection and evaluation How to choose hyper-parameters without fooling yourself, and how to report a number someone can trust. Cross-validation from scratch, pipelines that make leakage impossible, grid search on a DNA splice-site problem, the confusion matrix, precision, recall, ROC, and learning curves to tell bias from variance. k-fold · stratification · Pipeline · GridSearchCV · confusion matrix · precision/recall · ROC AUC · learning curves 07 Decision trees A model you can read like a flowchart. Measure impurity with the Gini index, grow a CART tree recursively from scratch and check it against scikit-learn, then watch depth drive overfitting and see why a single tree is so unstable — the reason the next lesson exists. Gini impurity · greedy splitting · recursion · depth · overfitting · variance 08 Ensembles — bagging, forests and boosting Many weak or unstable models, combined, beat one strong model. Build bagging and AdaBoost from scratch, tune a random forest's feature sampling, read feature importances, write gradient boosting as "fit the residuals", and benchmark everything on 100,000 forest-cover samples — including a gradient-boosting run that falls apart without regularisation. bootstrap · bagging · random forest · max_features · feature importance · AdaBoost · gradient boosting · learning rate

Part III Unsupervised learning

Part IV Deep learning

11 A neural network from scratch Open the black box before using a framework. Activation functions and their derivatives, why sigmoids make deep networks forget how to learn, a two-layer network written in NumPy with backpropagation derived line by line, a gradient check that proves it right, and what the hidden units actually draw. neuron · activation functions · vanishing gradients · forward pass · backpropagation · chain rule · gradient check · mini-batch SGD 12 PyTorch and the training loop The framework that does lesson 11's calculus for you. Tensors with shapes, dtypes and devices, autograd checked against a hand derivation, the canonical training loop, SGD vs momentum vs Adam, the MNIST bug of forgetting to normalise the pixels, and early stopping with a checkpoint you can reload. tensors · dtype · device · autograd · nn.Module · DataLoader · optimisers · input normalisation · early stopping · checkpoints 13 Convolutional neural networks Networks that know they are looking at images. Why a dense layer is the wrong tool for pixels, what a convolution layer computes and how many parameters it costs, an MLP against a CNN on Fashion-MNIST, the overfitting of the class model and how batch norm, dropout, augmentation and a learning-rate schedule fix it — and what the learnt filters actually detect. convolution · weight sharing · pooling · Fashion-MNIST · overfitting · batch normalisation · dropout · data augmentation · feature maps 14 Architectures and transfer learning A short tour of the architectures that shaped deep learning, the residual connection that made very deep networks trainable — measured, not just asserted — and the most useful trick in applied deep learning: start from a network pretrained on ImageNet. With 1,000 labelled satellite images, a fine-tuned ResNet-18 reaches 96%. AlexNet · VGG · ResNet · residual connections · EfficientNet · ViT · pretrained features · linear probe · fine-tuning · EuroSAT

Part V Deep learning for vision

15 Object detection with YOLO Find every object in an image and draw a box around it. Intersection over union and non-maximum suppression written from scratch, what a detector outputs and how confidence thresholds and input resolution change it, detection/segmentation/pose with pretrained YOLOv8, and fine-tuning on a 36-image skateboard dataset I labelled — on a CPU, compared with my original GPU run. bounding boxes · IoU · non-maximum suppression · confidence threshold · input resolution · mAP · YOLOv8 · fine-tuning · segmentation · pose 16 Metric learning and face recognition Classifiers need every class at training time; recognising people does not. Learn an embedding where the same face lands close and different faces far apart, train it with the ArcFace angular-margin loss written from scratch, make it robust to face masks with occlusion augmentation, and enrol a new person from a single photo with a threshold you can justify. embeddings · cosine similarity · ArcFace · open-set recognition · verification · ROC · thresholds · occlusion augmentation 17 Generative models — diffusion From recognising images to creating them. Build a denoising diffusion model from scratch — forward noising, a network that predicts noise, and the reverse sampling loop — watch it turn Gaussian noise into a learnt distribution, then see how the same idea, moved into a latent space and conditioned on text, becomes Stable Diffusion. generative models · DDPM · noise schedule · denoising objective · ancestral sampling · latent diffusion · classifier-free guidance